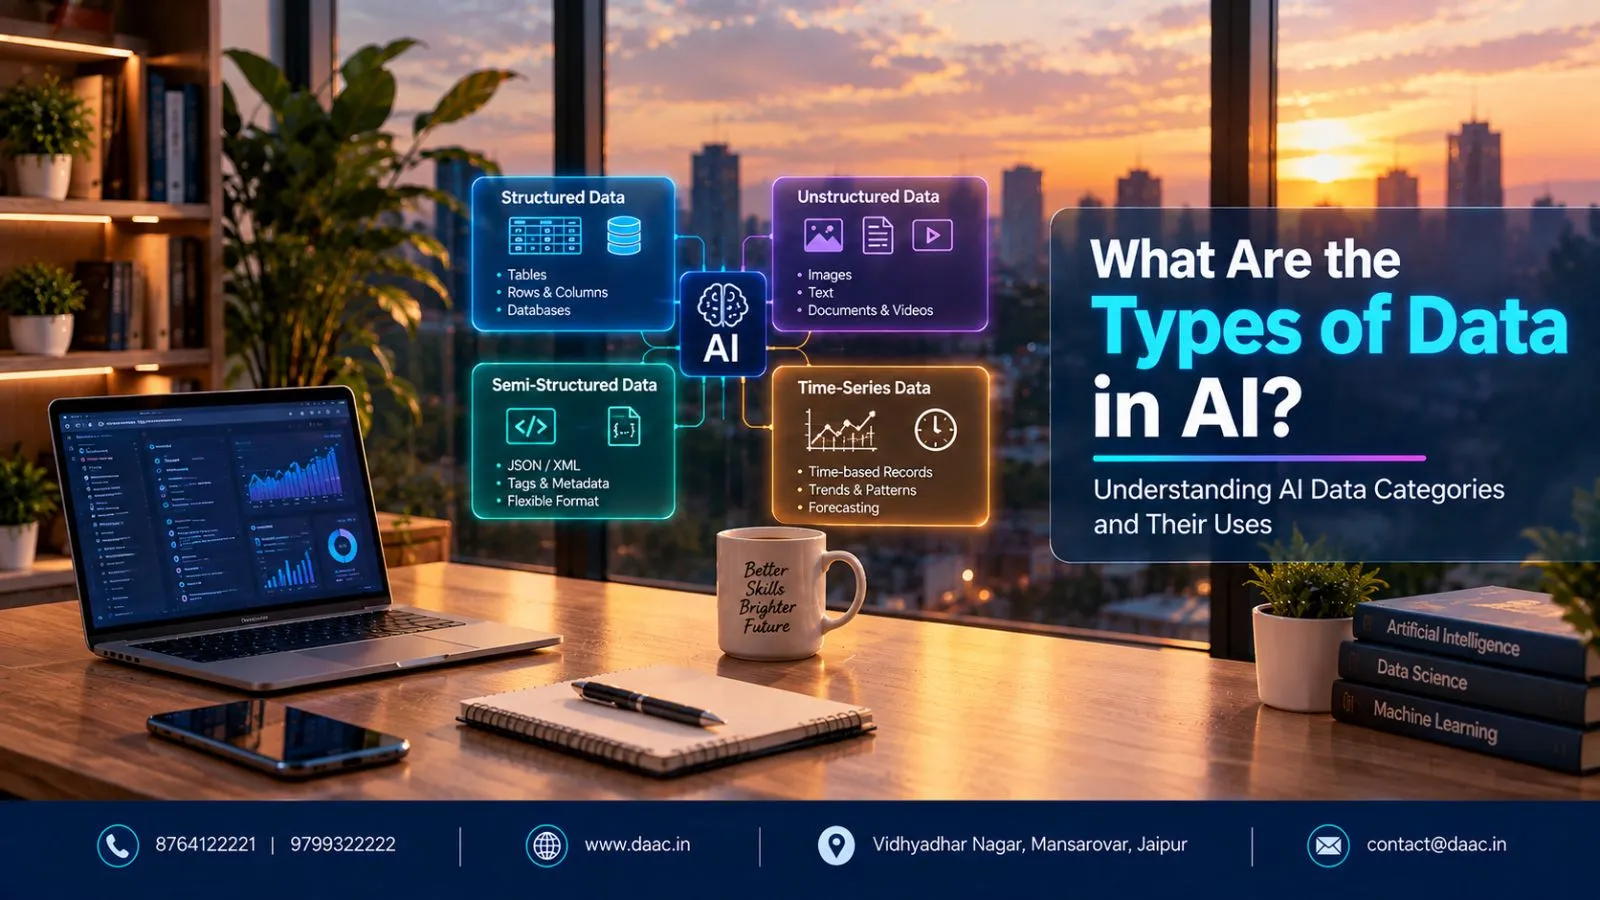
If you are wondering what are the types of data in AI, the answer goes beyond simple numbers and spreadsheets. Artificial intelligence systems can work with text, images, videos, audio, sensor readings, databases, documents, and many other forms of information. The type, quality, structure, and labeling of this data can directly affect how an AI system learns and performs.
As AI becomes more multimodal and is used in areas such as healthcare, finance, education, robotics, software development, and content generation, understanding data in AI has become an important skill for students and technology professionals. Modern AI evaluation is also increasingly concerned with performance across diverse datasets, modalities, and real-world tasks.
Introduction to Data in Artificial Intelligence
What Is Data in AI?
So, what is data in AI?
Data in AI refers to the information used by artificial intelligence and machine learning systems to learn patterns, make predictions, classify information, generate outputs, or make decisions.
For example:
- Customer records can help predict purchasing behaviour.
- Images can train systems to identify objects.
- Text can help language models understand patterns in language.
- Audio can support speech recognition.
- Sensor data can help machines understand physical environments.
The same information can also be classified in different ways. A customer database may be structured data, while customer reviews may be unstructured text data.
This is why understanding AI data requires looking at both its structure and its content.
Why Data Is Essential for AI Systems
Data provides the examples from which machine learning systems identify patterns.
Consider an AI system designed to recognise cats in photographs. It needs many suitable examples showing what a cat may look like in different environments, positions, lighting conditions, and image qualities.
If the training dataset is too small, poorly labelled, unbalanced, or unrelated to the real-world task, the model may perform poorly even if the underlying algorithm is sophisticated.
Modern AI development therefore focuses not only on models but also on data preparation, quality, representativeness, evaluation, and monitoring.
How AI Models Learn from Data
The learning process depends on the AI technique.
In supervised learning, models learn relationships between inputs and known labels. In unsupervised learning, models can identify patterns or structures in data without predefined labels. Reinforcement learning is different because an agent learns through interaction and feedback such as rewards or penalties.
A simplified AI workflow looks like this:
Collect → Clean → Prepare → Train → Evaluate → Deploy → Monitor
This is important because data does not stop being relevant after training. AI systems may behave differently when they encounter new real-world inputs, making ongoing evaluation and monitoring important.
Main Types of Data in AI
One of the most common ways to understand types of data in AI is by looking at how the information is organised.
Structured Data
Structured data is organised into a predefined format, usually rows and columns.
Examples include:
- Customer databases
- Sales records
- Financial transactions
- Employee information
- Product inventories
- Examination records
A spreadsheet containing customer age, location, purchase amount, and purchase date is a simple example.
Structured data is relatively easy for traditional database systems to store and query. It is also useful for machine learning models that work with numerical and categorical features.
Semi-Structured Data
Semi-structured data does not follow a rigid table format, but it contains identifiable structures or tags.
Examples include:
- JSON
- XML
- HTML
- Log files
- Metadata
- API responses
For example, an API may return customer information as a JSON object containing fields such as name, location, order history, and preferences.
Semi-structured data is especially common in modern web applications and software systems because applications constantly exchange information through APIs and structured formats.
Unstructured Data
Unstructured data does not follow a fixed database structure.
Common examples include:
- Documents
- Emails
- Images
- Videos
- Audio recordings
- Social media posts
- PDFs
- Customer reviews
A large percentage of business information exists outside traditional database tables. This makes unstructured data particularly important for modern AI systems.
Current data-classification practices also emphasise the need to identify and properly manage unstructured information because it can contain valuable or sensitive content.
Data Types Based on Content Format
Another way to understand artificial intelligence data is by examining what the data actually contains.
Text Data
Text is one of the most widely used forms of AI data.
Examples include:
- Articles
- Books
- Emails
- Chat conversations
- Product descriptions
- Customer reviews
- Search queries
- Technical documentation
Text data can be used for sentiment analysis, search, summarisation, classification, question answering, translation, and generative AI.
Modern language models process enormous amounts of textual information to learn relationships between words, concepts, and patterns.
However, text data also requires careful quality control. Incorrect, duplicated, biased, outdated, or misleading information can affect the usefulness of an AI system.
Image and Video Data
Images and videos are important for computer vision and multimodal AI.
Image data can be used for:
- Object detection
- Face analysis
- Medical imaging
- Quality inspection
- Document processing
- Visual search
- Autonomous systems
Video adds a time dimension because the AI system must analyse sequences of frames and potentially understand movement or events.
Modern AI evaluation is increasingly designed around multiple modalities, including image-based tasks involving vision-language models. Current evaluation programmes are testing AI systems across areas such as genomics, public safety, and scientific applications.
Audio and Sensor Data
Audio data includes speech, music, environmental sounds, and recordings.
AI can use audio for:
- Speech recognition
- Voice assistants
- Speaker identification
- Audio classification
- Transcription
- Sound-event detection
Sensor data is different but equally important.
Sensors can produce information about:
- Temperature
- Motion
- Pressure
- Location
- Acceleration
- Heart rate
- Machine conditions
Robotics, industrial systems, smart devices, and autonomous technologies can combine sensor data with other forms of information to understand changing environments.
Data Classification for AI Training
The data used in AI can also be classified according to how the model learns from it.
Labeled Data
Labeled data contains information about what each example represents.
For example:
| Input | Label |
|---|---|
| Image of a dog | Dog |
| Image of a cat | Cat |
| Spam | |
| Not Spam |
These labels provide learning signals for supervised machine learning.
Data labeling can involve humans, automated systems, or combinations of both. High-quality labels help models learn more reliable relationships between inputs and expected outputs.
Unlabeled Data
Unlabeled data does not have predefined answers attached to each example.
For example, a collection of thousands of customer reviews may contain text without labels such as “positive,” “negative,” or “neutral.”
Unlabeled data can be useful for discovering patterns, clustering information, representation learning, and other machine learning approaches.
It can also be valuable for large-scale AI systems because manually labeling every piece of information can be expensive and time-consuming.
Reinforcement Learning Data
Reinforcement learning uses a different concept.
Instead of giving the system a correct label for every action, an AI agent interacts with an environment and receives feedback.
For example, a robot learning to navigate an environment could receive a positive reward for reaching a target and a negative outcome for making an undesirable move.
The agent gradually learns which actions produce better results.
This makes reinforcement learning particularly useful for sequential decision-making problems.
Emerging AI Data: Multimodal and Synthetic Data
Modern AI is expanding beyond traditional categories.
Multimodal AI Data
Multimodal AI systems can work with combinations of text, images, audio, video, and other information.
For example, an AI system could receive:
Image + Text Question → AI Response
Or:
Video + Audio + Sensor Information → Event Analysis
This is becoming increasingly important as AI systems move into real-world applications.
Synthetic Data
Synthetic data is artificially generated data designed to represent useful characteristics of real-world information.
It can be useful when real data is limited, expensive to collect, difficult to label, or sensitive.
However, synthetic data is not automatically high quality. Its usefulness depends on how accurately it represents the intended real-world conditions.
This makes data validation important even when the dataset is generated rather than collected directly.
Importance of Choosing the Right AI Data
Having a large dataset does not automatically produce a good AI model.
The quality and relevance of data matter.
Improving Model Accuracy
Relevant and well-prepared training data can help a model identify meaningful patterns.
Data preparation may include:
- Removing duplicates
- Handling missing values
- Correcting errors
- Standardising formats
- Checking labels
- Removing irrelevant records
- Separating training and evaluation datasets
A model trained on poor-quality data may learn patterns that do not represent the actual problem.
Reducing Bias and Errors
AI systems can reproduce or amplify problems present in their data.
For example, if a dataset underrepresents certain groups, locations, languages, or situations, the resulting AI system may perform differently across those groups.
NIST guidance highlights the importance of examining training and evaluation data for completeness, representativeness, balance, subgroup coverage, and potential sources of bias.
Therefore, data quality should include more than accuracy. It should also consider coverage, representation, consistency, relevance, and potential bias.
Enhancing AI Performance in Real-World Applications
An AI model can perform well during development but behave differently after deployment.
Why?
Real-world data changes.
Users may ask different questions. Environments may change. New products may appear. Sensor conditions may vary. Language and behaviour may evolve.
This is sometimes described as data or distribution shift.
That is why modern AI development increasingly includes post-deployment monitoring. NIST’s 2026 work highlights the need to monitor deployed AI systems for functionality, operational behaviour, and unexpected outcomes in real-world environments.
How to Choose Data for an AI Project
If you are working on an AI project, ask these questions before training a model:
- What problem am I solving?
- What type of data represents this problem?
- Is the data relevant to the target users or environment?
- Does the dataset contain enough useful examples?
- Is the data correctly labelled where required?
- Are there duplicates, errors, or missing values?
- Does the dataset represent different relevant cases?
- Could the data contain sensitive or private information?
- How will the model be evaluated?
- How will performance be monitored after deployment?
This approach shifts the focus from simply collecting “more data” to collecting better and more appropriate data.
Final Thoughts
Understanding what are the types of data in AI is a fundamental step for anyone learning artificial intelligence and machine learning. Data can be structured, semi-structured, or unstructured. It can also appear as text, images, video, audio, sensor readings, labeled examples, unlabeled information, or reinforcement-learning experiences.
In 2026, the discussion around AI data is becoming broader. Multimodal systems, synthetic data, data quality, bias management, evaluation, and real-world monitoring are becoming increasingly important alongside traditional AI training data.
The key lesson is simple: AI performance depends not only on the model but also on the data, preparation, evaluation, and real-world context surrounding it.
For students learning AI, understanding these data categories provides a strong foundation for later topics such as machine learning, deep learning, computer vision, natural language processing, generative AI, and data analytics.